Fifty-Eight Blocked AI Tasks and a Living Room That Refuses to Go Dark

A Tolkien-named AI review committee gridlocked behind an API quota tollgate while hyperactive smart home sensors blast stadium spotlights across movie night

     If you want an honest glimpse into modern automated software engineering, look at what happens on a Saturday morning when your bot fleet hits an invisible tollgate. I logged into my dashboard to check on my AI minions, only to find fifty-eight blocked tasks staring back at me on the kanban board. Everything had ground to a dead stop. A cloud coding assistant had spent the night churning through pull requests; however, the moment my primary reviewer bot tried to audit the diffs, it ran straight into a provider quota wall. Fifty-eight automated code reviews, PR approvals, and dependency checks were frozen in place because one model had burned through its hourly token allowance.

     The culprit was Mandos, my local review bot. He sits in the pipeline reviewing code changes alongside Frodo, Gollum, and Aragorn; but when a cloud model starts spitting out dozens of minor refactors, a high-end review model eats rate limits for breakfast. To free up the pipeline, I stepped in with a quota governor script - leasing Mandos to a medium local model under a twenty-four hour lease. I fired off an immediate wake-up heartbeat, watched the fifty-eight pending tasks start draining cleanly across the board, and made a mental note to throttle concurrency later that night so the committee would stop slamming into provider walls. The future of autonomous coding, it turns out, involves a lot of waiting around in digital traffic.

     You would think stepping away from the keyboard to relax on the couch would offer an escape from rogue automations, but my living room had other plans. I sat down to watch a movie on Netflix, hoping for some quiet downtime; however, my smart home decided our living room needed the lighting scheme of a police interrogation. Every time someone shifted on the sofa or reached across the table for a handful of popcorn, the motion sensors tripped. Instantly, the lights blasted to full brightness, completely ignoring the television playback state. There is nothing quite like having a dramatic movie climax interrupted by stadium spotlights because you reached for a snack.

     It is kind of my fault; let me explain. The cool part, is that as I was on my way out the door, I pulled out my phone and spoke a prompt into the Antigravity remote webapp/page. It described what I wanted, and it knew how to use my Obsidian notebook to find the "production" home assistant instance, find all the automations, and do the stuff. It was just as easy as telling a voice assistant to turn off all the lights. Anyway, all the lights in the house turned off, the driveway light didn't turn on when I walked through the garage door, so I knew the automations were disabled, so I closed the garage door from my watch and rode my bike to find the kids (they were with their mom).

     You see, it was Halloween, so I hastily had AI create a "Dark Mode" switch to turn off all the light-based automations and turn the lights off. We normally do this because nobody comes to our house for Halloween, but we also leave a bowl of candy out near the end of the driveway just in case a straggler comes down our street. In my haste, I decided to trust in AI to get the job done without testing the outcome first (I was running behind, the kids were already trick or treating without me.) It worked to shut down the house before I went out; however, not quite everything came back online when I turned Dark Mode off. The final silver lining, is one more prompt to AI and it seems to have fixed things well enough; I have reviewed the tagged resources (always have an audit trail with AI does stuff) and the house lighting systems all seem to be functioning normally (I.E. I never touch a light switch to control a light.)

     One more lesson for the books; AI always seems impressive on the surface, but autonomous agent swarms that update your smart home while you are running out the door is beyond what actually works today. In practice, modern engineering feels like an endless cycle of building kill switches and babysitting chaperones. If you are not creating solutions to prevent an AI bot army from burning your GitHub actions quota in a few days, you are searching through your audit trail to try and figure out where things went wrong. We have more automated horsepower than ever, but half the job is just keeping the machines from stepping on their own feet.

Later,
     SteveO

Teaching Cloud Agents to Mirror GitLab (When They Only Speak GitHub)

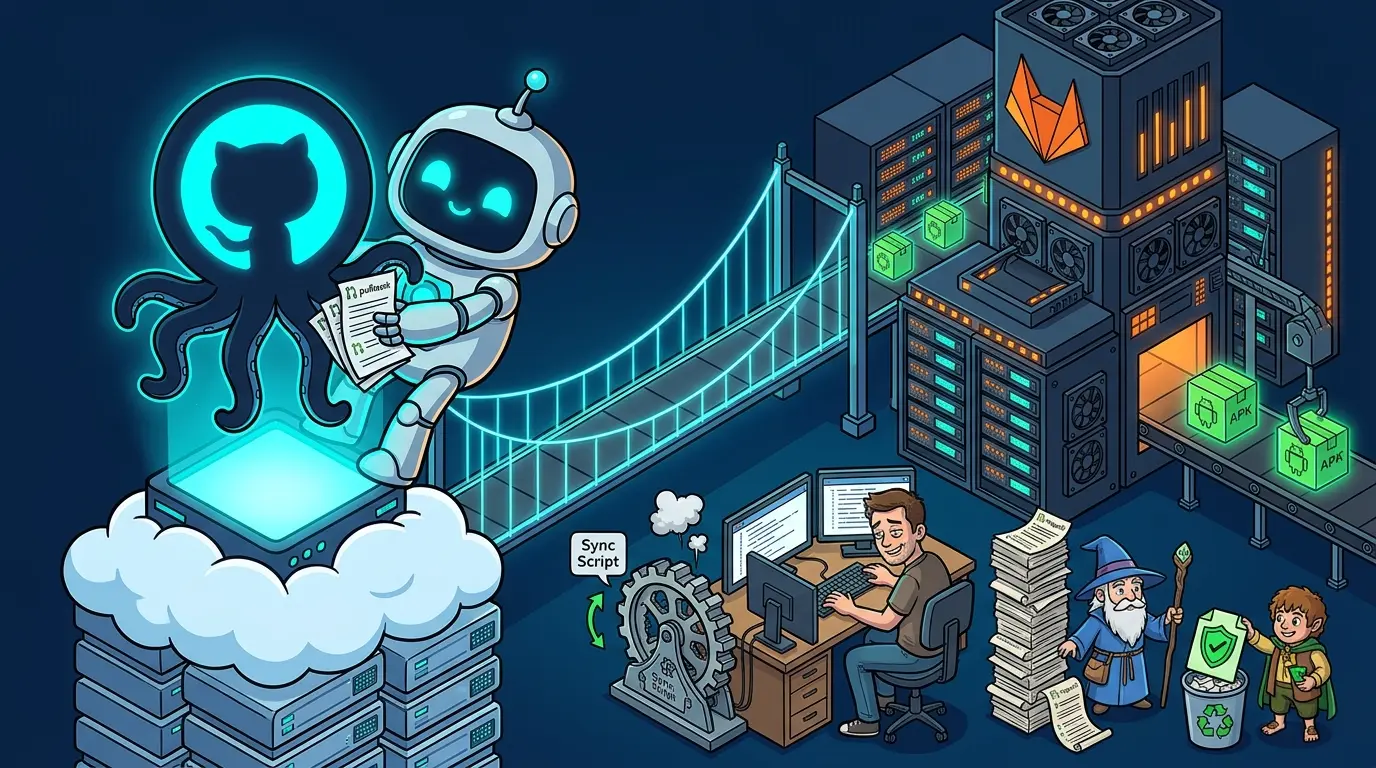
Google Jules clinging to GitHub like a security blanket while my local sync daemon tries to push code to self-hosted GitLab without choking on race conditions

     If you want a humbling lesson in the limits of cloud AI, try convincing an autonomous agent to acknowledge any version control system that isn't blessed by its creator. Over the past couple of days, thirty new suggestions rolled in from Google Jules across my personal repositories. Having an AI throw thirty suggestions at you before you even pour your morning coffee is a strange experience; it feels less like having an elite pair programmer and more like managing an over-eager intern who drank three Red Bulls and started refactoring everything in sight.

     I've actually refined this process a little. See, I just click start on all of them, then rely on my local triage squad of agents to work through the pile. Out of thirty suggestions, they threw thirteen in the trash. Most of those rejected items were classic AI churn; cosmetic whitespace changes, duplicate lint passes, and redundant null checks that did not actually fix anything. But a handful of them genuinely mattered. They caught and patched real path traversal security vulnerabilities, some minor bug fixes, and cut two clean releases before dinner.

     That seems great, until you see the exponential rise in Github Actions usage. So, the small taste of productivity put me into a strange situation; I eat through my entire free quota of Github actions in less than a week. The only real choice that gives me is to pay money or self host the pipeline. I spent the afternoon setting up a self-hosted GitLab pipeline on my homelab for Gas-Logger, complete with automated Gradle test runs, APK builds, and deployment hooks. Since Jules was already churning out code suggestions, I figured: why not point the agent directly at my self-hosted GitLab instance instead of keeping everything chained to GitHub? It took about five minutes of digging through the Jules documentation to realize that was never going to happen; the underlying bot source is fundamentally hardcoded to GitHub OAuth and repository IDs. The cloud agent literally refuses to leave GitHub.

     Because the AI clings to GitHub like a security blanket, I had to build a chaperone. I wrote a Python daemon to run on my homelab server, polling GitHub for merged changes, release tags, and open branches, and mirroring them over to GitLab. Distributed systems immediately reminded me who is boss; the sync script developed an annoying race condition (because of course it did) where tasks marked themselves done before git had actually finished pushing the branch. I had to hunt down the timing bug and rebuild the sync routines across all three repositories so my local CI runners did not try to build phantom commits.

     Everyone online keeps hyping the fantasy of AI agents writing entire applications from scratch while we sip drinks on a beach, but that has not been my reality at all. In practice, you spend half your day babysitting their vendor lock-in, hunting down stupid race conditions in custom mirror daemons, and filtering out forty percent of their output because it is pure noise. Having AI catch a real storage vulnerability is neat, but when tons of automated motion amounts to so much maintenance plumbing, you have to wonder where the busywork ends and the actual value begins. I suppose fixing the plumbing is still my job.

Later,
     SteveO

28 Pull Requests Before Midnight (And Why My Cloud Agents Need a Chaperone)

P.S. Thank you Nano Banana for the graphic, it emphasizes the issue in a strange way... more AI slop for the Internet!

     There is a specific panic that hits at twenty minutes to midnight, when you casually click a few repository suggestions in Google Jules and realize a cloud agent has opened twenty-eight pull requests against your main branch. Having an AI hunt down security bugs while getting ready for bed sounds great; in reality, every single pull request instantly spun up a production GitHub Actions runner (which will chew through monthly CI minutes faster than anything else I know).

     The fixes themselves were actually solid. Jules tore through three of my personal projects (NL-Nutrition, SuperBudget, and Gas-Logger) like there was no tomorrow. It patched path traversal holes in Gas-Logger across PRs; it closed an SQL injection risk (I think... who knows really) in NL-Nutrition; it locked down CORS origin rules in SuperBudget; and it migrated brittle date parsing to thread-safe DateTimeFormatter calls before expanding unit tests. Part of me was thrilled to see tedious cleanup handled in twenty minutes - the code was cleaner, test suites were fatter, and I only clicked a button and had paperclip agents push the code through a multi-agent (Antigravity, Claude, and Codex) until it was merged to... main?

     The problem is that cloud agents do not pay your cloud bills. When Jules finishes a batch, its instinct is to aim straight for main; meaning my repositories started kicking off full integration suites and Docker builds all at once. Luckily, I built a local chaperone. My homelab server runs a daemon called jules-governor that wakes up every ten minutes, scans GitHub, and quietly re-targets open Jules PRs from main over to develop. That simple switch diverts the flood into lightweight test runs so GitHub Actions does not eat my lunch before breakfast; truly a lifesaver when letting autonomous bots roam free in your repositories.

     This late-night circus capped off an already wild day of agent operations. Earlier that morning, my local homelab fleet was running its own patrol rounds. Across a three-node Proxmox cluster with twenty-one network hosts and ten active virtual machines, local agents like Aragorn, Frodo, and Gollum (yea, LoTR themed agent names :) audited backups and verified services. Meanwhile, my Home Assistant edge setup (which reports device telemetry to an analytics cloud platform for senior care) ran 1,799 unit and integration tests, alongside 73 UI test suites, against a local Home Assistant Green hub and simulated apartment. So, on paper, I have over 90% of the code tested end to end, but does that really mean any of this crap works?

     Even with twenty-one healthy local agents and hundreds of completed Paperclip tasks under my belt, reality still taps you on the shoulder. By afternoon, two code-review tickets (where Mandos audits a worker teardown fix) sat frozen in blocked status; all because I had burned through my weekly Claude quota and had to wait for the counter to reset. I mean, what is the point of having an AI company if it grinds to a halt because of a quota? Building software with autonomous agents feels like magic when dozens of security fixes land in your lap before midnight; however, the uncomfortable truth is that half the engineering job now is building governors, branch routers, and rate-limit safety nets to keep your digital helpers from lighting your compute budget on fire.

     Anyway, this rant doesn't have a real point. Just marveling at the way tons of work amounts to nothing in particular. Its almost like AI never crossed that bridge from busy work to delivering value. I guess that's my job?

Later,
     SteveO

I Vibe Coded a Thing... It Was Fun

     If you read Part 2 of my agentic development series, you already met Sleepy Tom, Baking Martha, and the rest of the Virtual Villa residents (none of whom exist, which makes them very easy neighbors). This one is a quick side trip into how the thing actually got built.

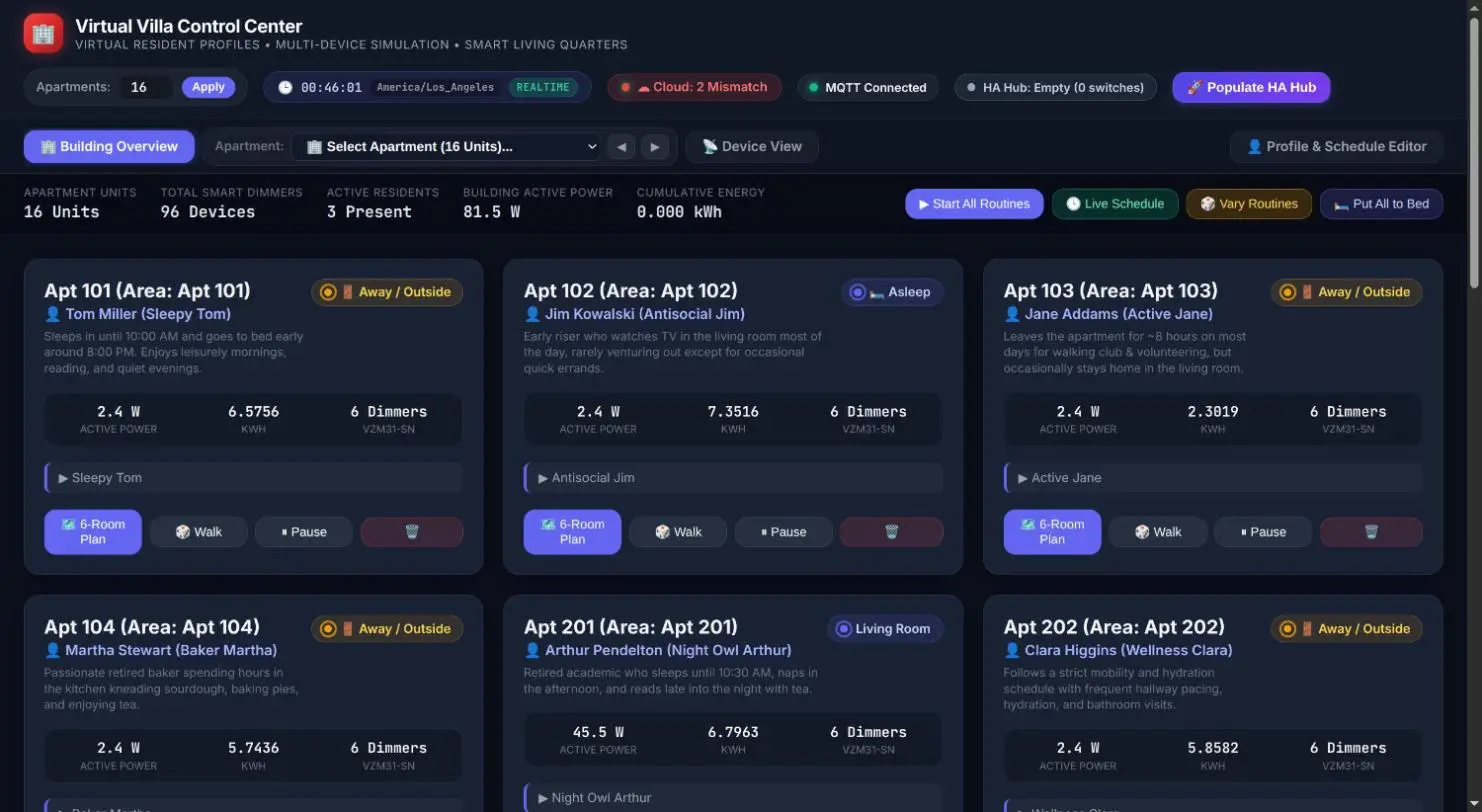
The resident roster (16 apartments, down from 24; more on that later)

     There is a real adrenaline rush in telling an AI to do something, watching it go do it, and then fiddling around in the UI instead of solving the programming problem myself. Solving those problems is a different kind of challenge, and one I would miss if I couldn't do it regularly; however, for a couple of weeks it was a blast to just let the AI take the reins.

     A lot of this I did by talking to Google Antigravity on my phone. I tried to keep my hands off the keyboard, and I didn't always manage it. I would describe what I was seeing (residents stuck, lights not turning on, the apartment count resetting) and Antigravity would find the cause, fix it, run its tests, commit, and push. Every time it wrote a file, its own tooling reminded it "Don't ask for permission" - and it mostly didn't. It even built the disposable Home Assistant VM on my Proxmox server with Terraform, and later logged into the host itself to snapshot and upgrade it whenever I asked. Near the end, going from my request to a pushed commit usually took 8 to 18 minutes.

     Everything runs on local IP addresses with no domain name, and the test VM rolls back to a snapshot, so breaking things was kind of the point. I think a sandbox like that is essential when you hand an AI the keys. That said, my idea of "isolated" was a little optimistic... the supposedly empty test hub went and found my real TV and Sonos speakers, and a "Mickey Mouse Speaker" from my home setup kept coming back from the dead.

     Every room in Virtual Villa has a fake Inovelli Red Series dimmer with presence sensing. At first they showed up in Home Assistant as generic MQTT devices, even after Antigravity copied my real switch's model and firmware details (straight out of my production Home Assistant, no less). So one morning I just asked whether they could be actual Z-Wave devices. Antigravity explained that Home Assistant labels a device by the integration that created it, and when I said yes, it wrote a mock Z-Wave server. It committed at 10:54, and by 11:11 Home Assistant believed it had 145 Z-Wave devices (144 dimmers across 24 apartments, plus the controller).

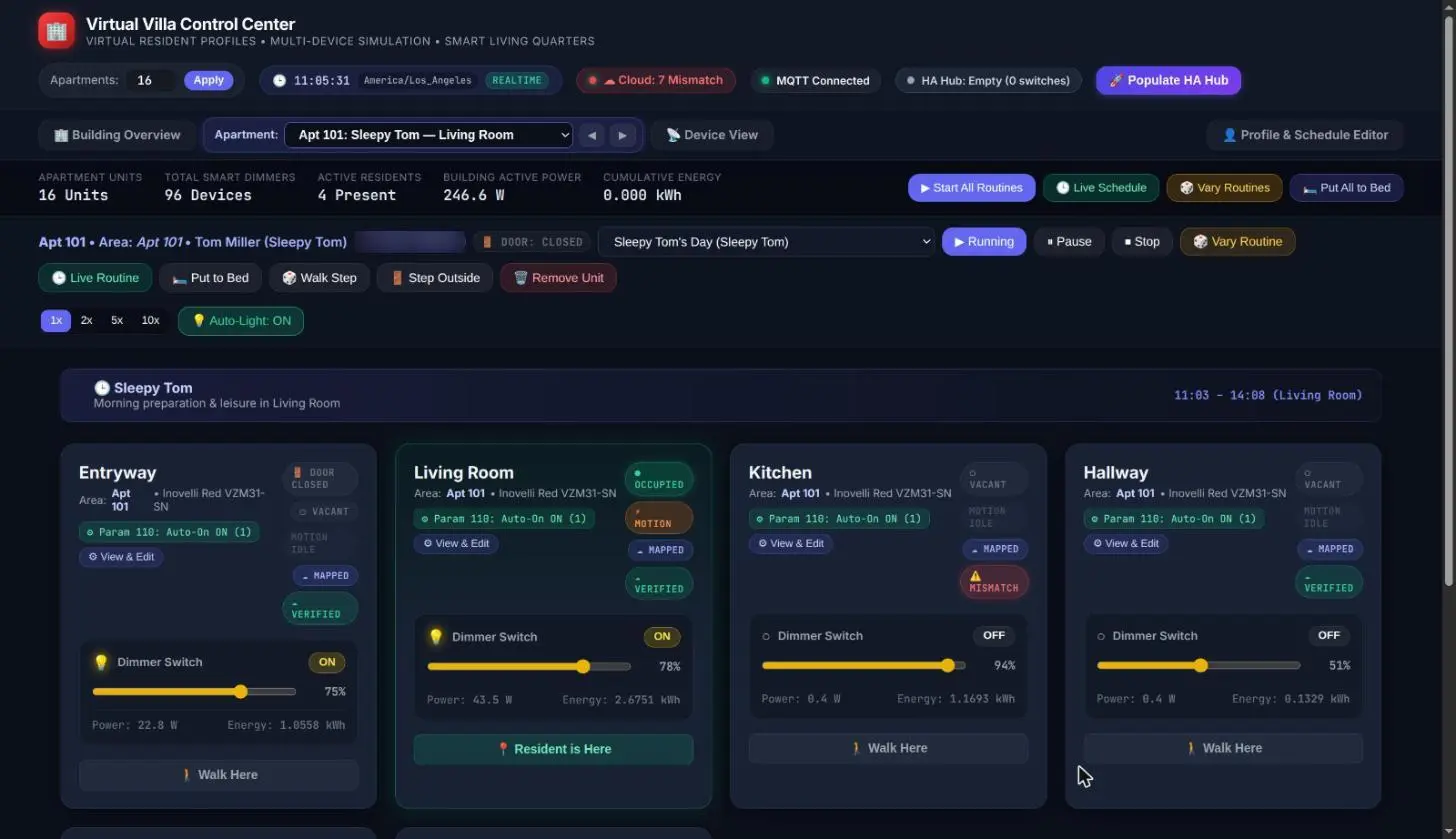
Sleepy Tom is up and about, and the cloud agrees with every room shown here except the kitchen

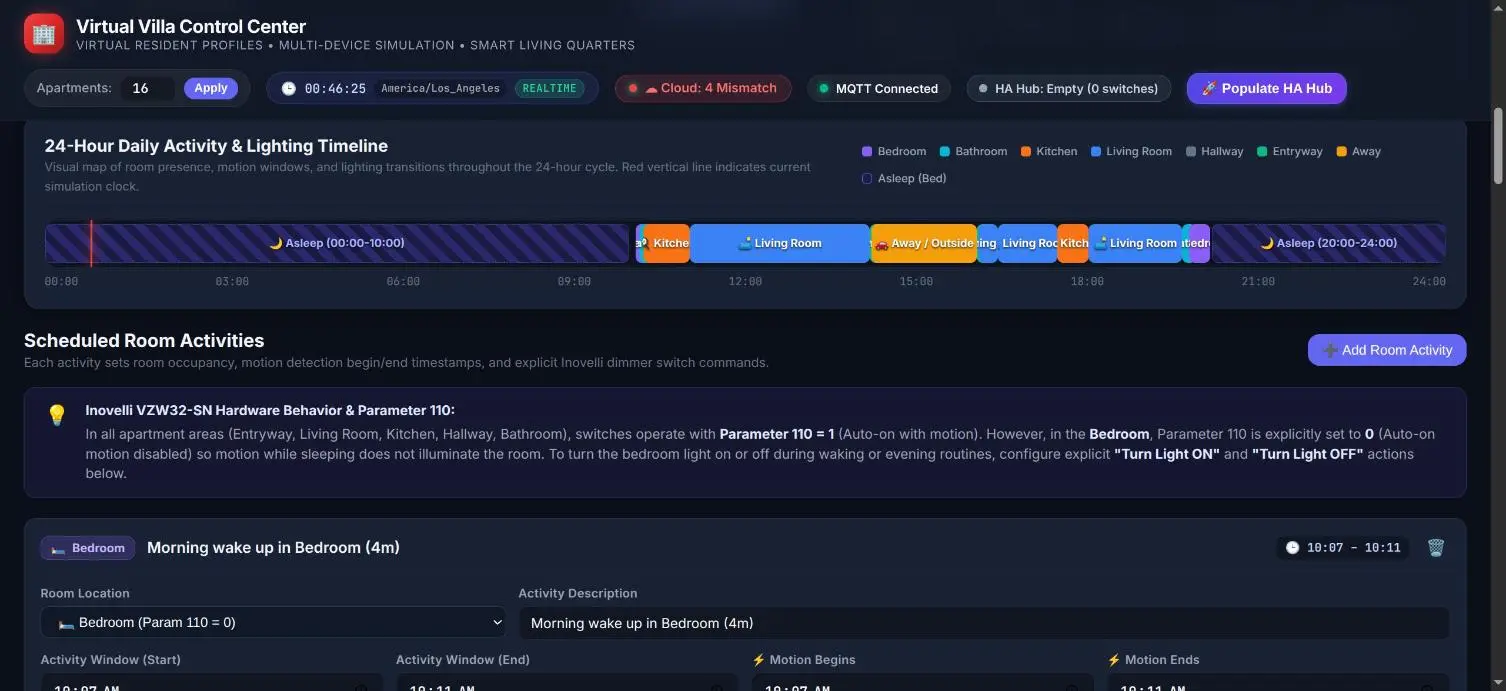
     My job was playing product owner, and that started well before the Z-Wave work. I wrote the first three residents myself: Sleepy Tom, Antisocial Jim, and Active Jane (I called him Jack in Part 2; he hasn't complained, because he doesn't talk to anyone). Antigravity filled out the rest of the building with folks like Night Owl Arthur and Wellness Clara. I described their days in plain English: meals take 30 to 60 minutes, bathroom trips 1 to 10, and a trip out anywhere from 10 minutes to 8 hours. Motion turns the lights on just like the real switch, except in the bedroom; nobody wants the light coming on every time Sleepy Tom rolls over.

Sleepy Tom's day: up at 10 AM, back in bed by 8 PM (living the dream)

     I also had it read the sun position from Home Assistant so the light sensors would feel real. In my head the bedroom and living room had big windows, the kitchen borrowed light from the living room, and the bathroom was a cave. Antigravity picked its own numbers (living room 100%, kitchen 70%, bedroom 60%, bathroom 8%)... not quite the apartment I pictured, but close enough for a test harness. Honestly, that was the fun of it: I spent my time picturing apartments instead of writing code, which is a nice break from the nitty gritty backend work I usually live in.

The kitchen light is off, so this 3.4 lux is all sun at 11 AM (either it was cloudy or the math needs work)

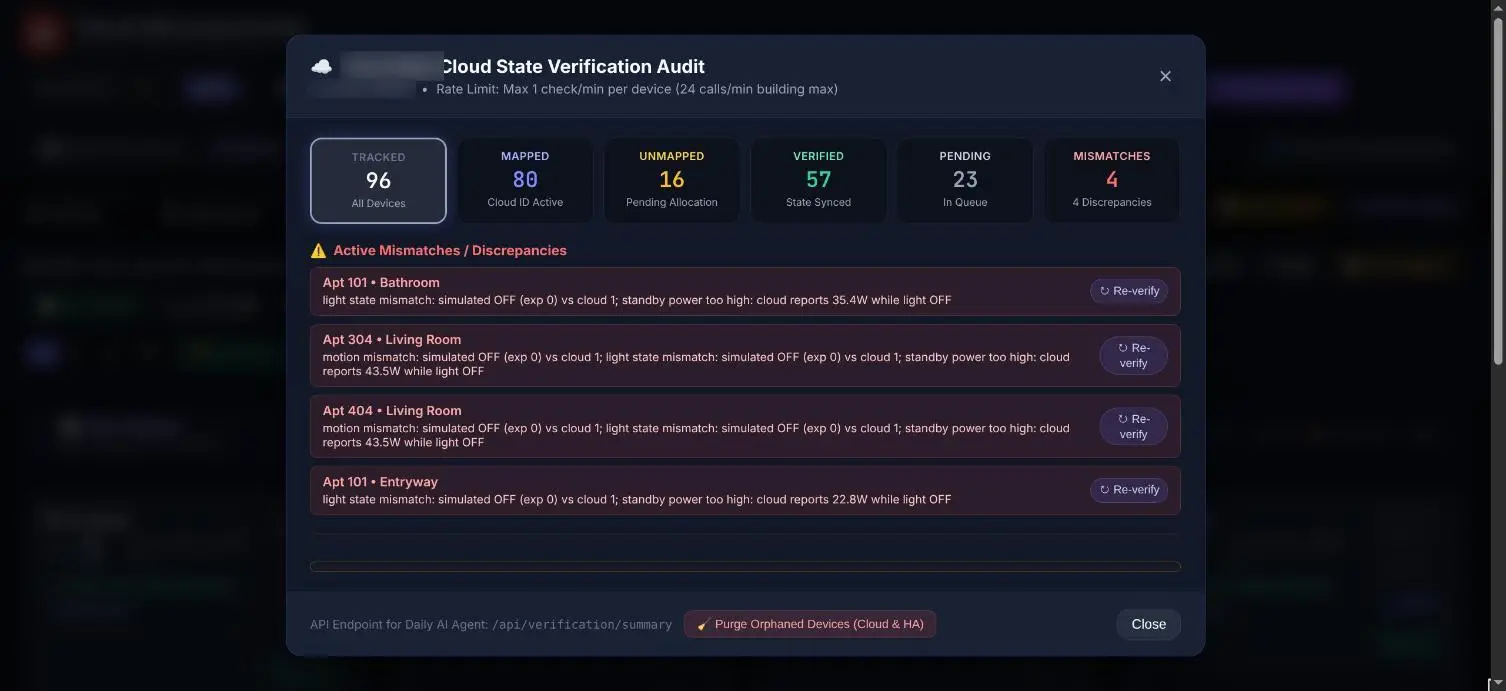
     The whole point was verification. Another project I work on, a Home Assistant app that reports device changes to an analytics cloud platform for senior care, needed proof that when a simulated light turns on, Home Assistant sees it and the cloud hears about it. During development the tests could hit Home Assistant's local API all day long; the cloud is a different story. A QA tool is more of a cost center than a value add, so I budgeted one check per device per minute, and later cut that back to device adds, hub changes, an hourly sweep, and the Re-verify button.

The cloud audit compares motion, on/off, dimming, and power; I don't know yet whether those mismatches are real bugs or the checker's own

     That 144-device stress test found a real limit, too. When devices went missing in the cloud, Antigravity blamed a container restart until I pushed back. Then it found a hard per-location device cap, so a few days later I cut the building to 16 apartments and 96 devices.

     I really do think this is where software development is headed. With a team of agents, I can do the work of five or six people. I do have to admit something, though... on this one, Antigravity was grading its own homework. It ran its own tests, pushed straight to main, and no second model reviewed anything, which is not quite the picture I painted in Part 2. I did set up a Claude reviewer in Paperclip partway through, but I never pointed Virtual Villa at it; in hindsight, that is exactly what this project was missing.

     The part that worries me is what this does to people early in their careers, which is what Part 3 was all about. If AI becomes a crutch, plenty of developers will ship code like this without knowing if it's any good. I haven't done a deep dive yet, but every task I gave it was focused on one small goal, so I fully expect duplicate logic everywhere (plenty of developers would call it AI garbage, and they might be right). It's fine for a throwaway QA tool - I am nearly positive it is not code I would want running in production.

     Anyway, that's all for now. In a future post I want to dig into the performance and the code to see where the AI cut corners; until then, I'm going to keep tinkering.

Later,
     SteveO

How I created my weekly feed digest

So, if you read the frizzlefry blog, then you probably noticed I had an issue today that was all about my weekly shared Items in Google Reader.  I have been thinking about reorganizing all of my shared feeds into a series of digests.  The nice part, is that other people did all the work for me, so all I need to do is put their work together into a script I can run.

So, where to start?  ok, first I want to parse out an Atom feed, so I chose the Universal Feed Parser which is a nice little utility to parse out RSS/Atom feeds among other stuff I'm not currently interested in.  So, because the library I wanted to use is in Python, I decided that I was going to write a little python script to get the work done... I guess the language of a library is as good a reason as any to choose your language.  '

Anyway, ok, so how does this thing work?  really simple as it turns out...
To start off, I import the feedparser library, and create a feed object:

import feedparser

d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')


So, that creates a variable d, which is a feed object.  All I want from the feed is the title and description, so I can access those simply by using:


import feedparser

d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')

d.entries[itemnumber].title
d.entries[itemnumber].description


However, I want to print out those values, which can be done with the print like this:


import feedparser

d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')

print d.entries[itemnumber].title
print d.entries[itemnumber].description


Next, I want itemnumber to mean something, so I'll put the whole thing together in a for loop that prints all entries like this:


import feedparser

d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')

for itemnumber in range(0, len(d.entries)):
   print d.entries[itemnumber].title
   print d.entries[itemnumber].description


Now, I wanted to make sure that I limit the list to only include items after a given start date that I could specify as a command line argument, so I added a couple more lines:


import feedparser

startdate = datetime.strptime(sys.argv[1],'%Y-%m-%d').date()
d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')

for itemnumber in range(0, len(d.entries)):
   print d.entries[itemnumber].title
   print d.entries[itemnumber].description
   if datetime.strptime(d.entries[itemnumber+1].published,'%Y-%m-%dT%H:%M:%SZ').date() < startdate: break


So, I created the startdate variable, which is a date provided by the command line in the format
--, then it breaks the loop if date published is before (less than) startdate. 

Finally, I wanted to add some basic HTML formatting to make it easy for me to copy and paste the text into blogger... that lead me to my final version of the python script, which looks a little like this:


import feedparser
from datetime import date
from datetime import datetime
import sys

print sys.argv[1]
startdate = datetime.strptime(sys.argv[1],'%Y-%m-%d').date()

d = feedparser.parse('http://www.google.com/reader/public/atom/user%2F11424318483849164397%2Fstate%2Fcom.google%2Fbroadcast')
print '<html><head><title>'

print d.feed.title
print '</title></head><body>'

for itemnumber in range(0,len(d.entries)):

print '<h1>'
print d.entries[itemnumber].title
print '</h1>'
print d.entries[itemnumber].description
print '<br /><br />Date Shared: '
print datetime.strptime(d.entries[itemnumber].published,'%Y-%m-%dT%H:%M:%SZ').date()

if datetime.strptime(d.entries[itemnumber+1].published,'%Y-%m-%dT%H:%M:%SZ').date() < startdate: break
print '<hr />'
print '<hr />'
print '<hr />'

print '</body></html>'


So, the first part of my script was done... I named the file GeneratePage.py, and proceeded to create three more files... the second file was SaveDate.py, which would simply output the date in the format I needed it using two lines:

from datetime import date
print date.today()


I figured the best way to track the previous time the script was run would be to save the date to a file, so I created a file called date.txt that contained only the string "2011-02-26".

Then I created a batch script that would tie everything together... the batch script looks like this:

#!/bin/bash
D=`cat date.txt`
python GeneratePage.py $D
python SaveDate.py>date.txt


This script would set the date from date.txt to a variable called D. Then it would run the GeneratePage.py script while passing it the value of D. Then it would run the SaveDate.py script, with the output replacing the contents of date.txt.

At this point, the script could be run every week, and the output can be copied and pasted into blogger.

The next step will be to automate the process of putting the dialog onto the site, which will actually take a little effort, but I'm pretty sure someone else has already done the work for me, I just have to figure out who did it.

Oh, on one other note, in case you are curious why I didn't just redirect all the output to a file, it's because some of the feed items use Unicode characters that cannot be converted to ASCII... so Bash gets angry when you do that.  I might be able to fix this easily, however, I really don't mind having to copy and paste the characters into the blog anyway.

Later,

     SteveO

Managing your Droid Incredible with Ubuntu 10.04 Linux

Hey everybody!  It sure has been a while since I updated this blog, but I think it's time I did.  Last week I picked up an HTC Droid Incredible, which is the Verizon version of the Incredible, and I've found that nobody has really written about what you can do with this thing using Ubuntu (a Debian-based Linux distribution.)  So, I'm here to tell you that you don't need a Windows PC to manage your device, and when I say that, I'm not implying you have to be a Linux expert or manually put all your files on the device.  So, to avoid most of that cryptic Linux stuff, I'm going to almost completely avoid the command line (I'll tell you the command, but I'll also tell you how to do it without the command...except for DVD playback, you have to copy and paste that command.)  I will also assume you have a default Ubuntu installation, so you may think I'm just being silly by installing some of this stuff.

Please note that I won't cover the mobile broadband functionality because the setup I have for it is very complicated and unstable at the moment.  Once I figure out a simple way for people to get it working, then I will write a post about it.

The super duper quick version


For those of you who know Ubuntu/Linux well, just install and configure the Restricted Extras Packages, libdvdcss2, Banshee, and Arista with this command (All of it is in the Ubuntu Software Repositories):

sudo apt-get install ubuntu-restricted-extras kubuntu-restricted-extras xubuntu-restricted-extras libdvdcss2 banshee arista; sudo /usr/share/doc/libdvdread4/./install-css.sh

Then you're setup is done.  Go to the section about Banshee if you want your device to display with the correct name and use the correct folder, and Arista is so simple, all you have to do is: choose a video file or DVD device as the source, select Ipod as your device, and Low as the Preset, then click Add to Queue (I can't really tell the difference between the low and high presets when using the device, but low uses half the memory.)


Codecs and DVD Playback

     So, let's spend a little time getting your system ready, and then our entire experience will be a little nicer.  First things first, you will want codecs for videos and music.  So, open up the Ubuntu Software Center (Applications -> Ubuntu Software Center), then type "restricted" into the search bar in the upper right corner.  You will see three packages that you want*: Ubuntu Restricted Extras, Kubuntu Restricted Extras, and Xubuntu Restricted Extras.  I don't think you really need all of them, but I always just install all three, so I'm going to tell you to do the same.

* Please note that the Restricted Extras Packages and the libdvdcss2 package are not allowed in some countries.  My primary audience is people in the US.

Ok, I kinda lied a little about the cryptic stuff thing... If you want to play back DVDs, you need to do one thing:

  1. Press Alt+F2 on the keyboard, and the Run Application dialog pops up.
  2. copy and paste this command into the Run Application dialog:
    "sudo apt-get install libdvdcss2; sudo /usr/share/doc/libdvdread4/./install-css.sh"
  3. Check the Run in terminal checkbox
  4. Click Run.
  5. A window with a bunch of text pops up, and I think you might have to hit "y" to accept the license agreement.
So, that wasn't too bad was it?  Because of restricted licenses, Canonical can't just distribute the DVD playback libraries with Ubuntu, so you have to get that separately and accept the EULA (End User License Agreement.)  Then you have to run a script that sets everything up for you; that is what the above command does.

Ok, now everything is set up, and you are ready to play all your music, watch movies, and all that kind of stuff.  

Media Management Software

Now, there are two more programs that you will want:  Banshee Media Player, and Arista Transcoder.  Both of these are available in the Ubuntu Software Center, so just type them both into the search box (one at a time of coarse) and you have all the software you need.  There is just one thing though, Banshee detects your Android Phone as a generic Android Device.  I don't mind the picture of the G1, but I just want the program to use the default music folder (/emmc/MP3/ for internal storage, or /sdcard/MP3/ for the microSD card), and I want the correct name for my phone.  This is actually a really simple thing to do.   You just create a text file, and save it to the device with a very specific name.

Get Ubuntu to See your Phone

By default, my phone goes into charge only mode when I plug it into a USB port, which you can change, but I like it that way.  So first, connect your phone to your computer.  Now, on the phone, open the notification area, tap the USB Icon that says "Charging Only" next to it, then select Disk Drive from the menu that appears.  Once your phone appears on your computer, you need to save a file into the root folder of the device.

The root folder would typically be called something like C:, D:, E:, etc... on a Windows computer.  You can recognize it because it shows up as a USB stick on the Places menu and on the side bar in the file browser (or in this case the save as window.)

Also note that if you have a MicroSD card, that will show up as a separate drive/device, You can set the name for the phone and MicroSD card separately in Banshee by repeating the following steps with a different name for the memory card.  You have to manage both of them separately.  Most software in the Android marketplace will not recognize media on the phone's internal storage yet, but if you just use MP3s and Ipod-formatted videos, you can just use the default media software on the phone.

Get Banshee to show the correct Name for your device:


Now that your device is connected and Ubunti can see it, you can save a text file to the device.  So, Open a text editor (Applications -> Accessories -> gedit Text Editor.) Then type two Lines (just copy the stuff between the quotation marks):
  • Line 1: "name=Droid Incredible"
        - This name can be what ever you want Banshee to call the device
  • Line 2: "audio_folders=MP3/"
        - This is an optional line; I chose to add it because I had already manually copied files to the MP3 folder, and now I wanted to keep everything simple.
Ok, now save that file as (File->Save As...) ".is_audio_player" and put it on the root of your device or SD card.  (You need the period at the beginning of the file, and the file has no extension at the end)  

Note that from now on, this file will be hidden, so to view the file in the file browser, you need to select View -> Show Hidden Files (or Press Ctrl+H.)

Ok, so now Banshee should show the name you specified, any music you have already put into the default folder, and sync new music to the folder you specified.

If you want a complete list of what you can put into the .is_audio_player file, you can refer to this page:

The Floccinaucinihilipilification Homepage - .is_audio_player file format by Darin Ohashi


Formatting Video for Your Device

So, after spending hours of trying different video transcoders, and different video players, I found that Arista Transcoder is the easiest option available.  You just open the program, choose a source, choose a device, choose a preset, and add to queue.  You can even queue up several video files and let them all go.  Then, when all is said and done, you can put the media on your SD card or the internal storage and play it through the photo browsing tool that came pre-loaded on the phone.

The source is either a DVD drive or video file.  For the device, just choose Ipod.  For the preset, choose low.  You can use High, but you will need to stop all non-essential processes or the video can go out of sync if you get an email or something.  Plus, the High preset uses twice as much memory, and I think about 200MB is much more reasonable than about 500MB.

Using Banshee

Banshee is really easy to use.  It will download album art, but it doesn't use the correct format for the HTC Incredible.  If you really need your album art, I have been using Media Monkey on Windows to update Album art directly on the device, and that works pretty well... I'll have a Linux solution soon, but that's not really a priority for me.

I've also found that playlists don't quite work right "out of the box."  I'll figure that out later, because I normally just press shuffle all, then stop looking at the device until I want to skip a song.

As far as video is concerned, you can just import everything to the library from the file menu.

At this point, you can use Banshee to sync all of your music and videos to your device in a very similar way to how you would sync everything with your iPod or other devices.  In fact, you can even use Banshee to sync to your iPod!  So, I hope this helps make every Ubuntu user that much happier with Android.

Check back soon to see updates on my favorite Android Apps, Linux tips, and general Tech stuff.

Later,

     SteveO

Google Wave First Impressions

So, I got an invite to the Google Wave Developer preview, and it's pretty cool.  It looks right on track for a beta at the end of September. It was a little funny at first because you just get this information overload right away.  Everything everyone was talking about flooded my inbox.  This was because of a special dev channel that you can subscribe to right when you sign up for your developer account.  Basically it's a constant stream of what the devs think is important to get done.  There is a lot going on.  Linking Wave to Google's App engine works pretty nice, and you can get a lot done with robots. So, dealing with the information overload lead me to use the search box a lot.  There was no way for me to read all the waves, they all just kept going.  Each wave would have a dozen or so people doing all sorts of things.  One wave was a group of people collaboratively creating a book, and another wave was a list of robots.  The most common waves I found were titled "test"  because that was what the channel was for.  Testing stuff that you are writing for Wave. Once you get used to the information just streaming in from everywhere, you start to like it.  You can search for anything you want, and real time results of waves on your channels start flowing in.  You can reply to waves, play games of chess, and even add hot spots to a map.  The conversation really just flows smoothly. Now that I'm getting in my groove, I started to wonder what kinds of cool stuff I can do with Wave.  I started looking for bots, and the robot wave just popped right up.  I saw the Twitter bot, Tweety the Twitbot, and then added the email address (tweety-wave@appspot.com) to my contact list.  The whole process to this point was just like any other bot (like smarterchild on AIM...)  Now I can start a wave, and include tweety.  From then on, anything you say in the Wave will end up on twitter.  So it's important not to use multiple bots in one wave... like I just did... you end up tweeting things like $MSFT... anyway, that tweet was supposed to be a wave for Stocky (stocky-wave@appspot.com) who actually changes the text you enter into a stock quote (like you type "$MSFT" and Stocky changes it to this "MSFT (25.56)".) The bots are awesome!  You can embed pictures, maps, surveys, polls, real time weather, HTML, and all sorts of stuff into a Wave.
Another cool thing I noticed right away is that everything can be minimized.  With the announcement of the Google Chrome OS, I can see Wave as evolving into some sort of live desktop.  You can have multiple waves open at once, and just switch between them.  The full screen reading mode will also be pretty nice for my netbook. In final, my first impression is that Google Wave will revolutionize the way people communicate on the web.  Everything is so easy to do.  Want the weather?  tell the weather robot where you want the weather for.  Stocks? Directions?  Microblogging?  Actually that makes me think, how will this effect twitter?  You have real time search, and a more interactive way to communicate with your friends! Anyway.  I was really excited about Wave before, and now that I've gotten a taste of it, I don't think I can stop.